
Google DeepMind announced Gemini 4 Argon on September 30, its new frontier model for long-horizon work in software engineering, legal and finance, and cybersecurity defense. It is not generally available yet. It is rolling out first to trusted cyber defenders through Google's Fairwind Program, and Google says it is taking part in the U.S. government's voluntary pre-release access process.
Argon will launch at an introductory price of $2 per million input tokens and $10 per million output tokens, with cached input 95% cheaper. The output limit rises to 1M tokens, up from 64K, so a single trajectory can run to hundreds of thousands of tokens.
Google compares Argon against GPT-6 Astra, Claude Fable 5.1 and Claude Opus 5.5. By its numbers, Argon is top or tied on 14 of 19 rows. The biggest margins are in knowledge work: Harvey's Legal Agent Benchmark (19.6% against 6.7% for the next model) and Vals Finance Agent v2 (65.4% against 58.9%).
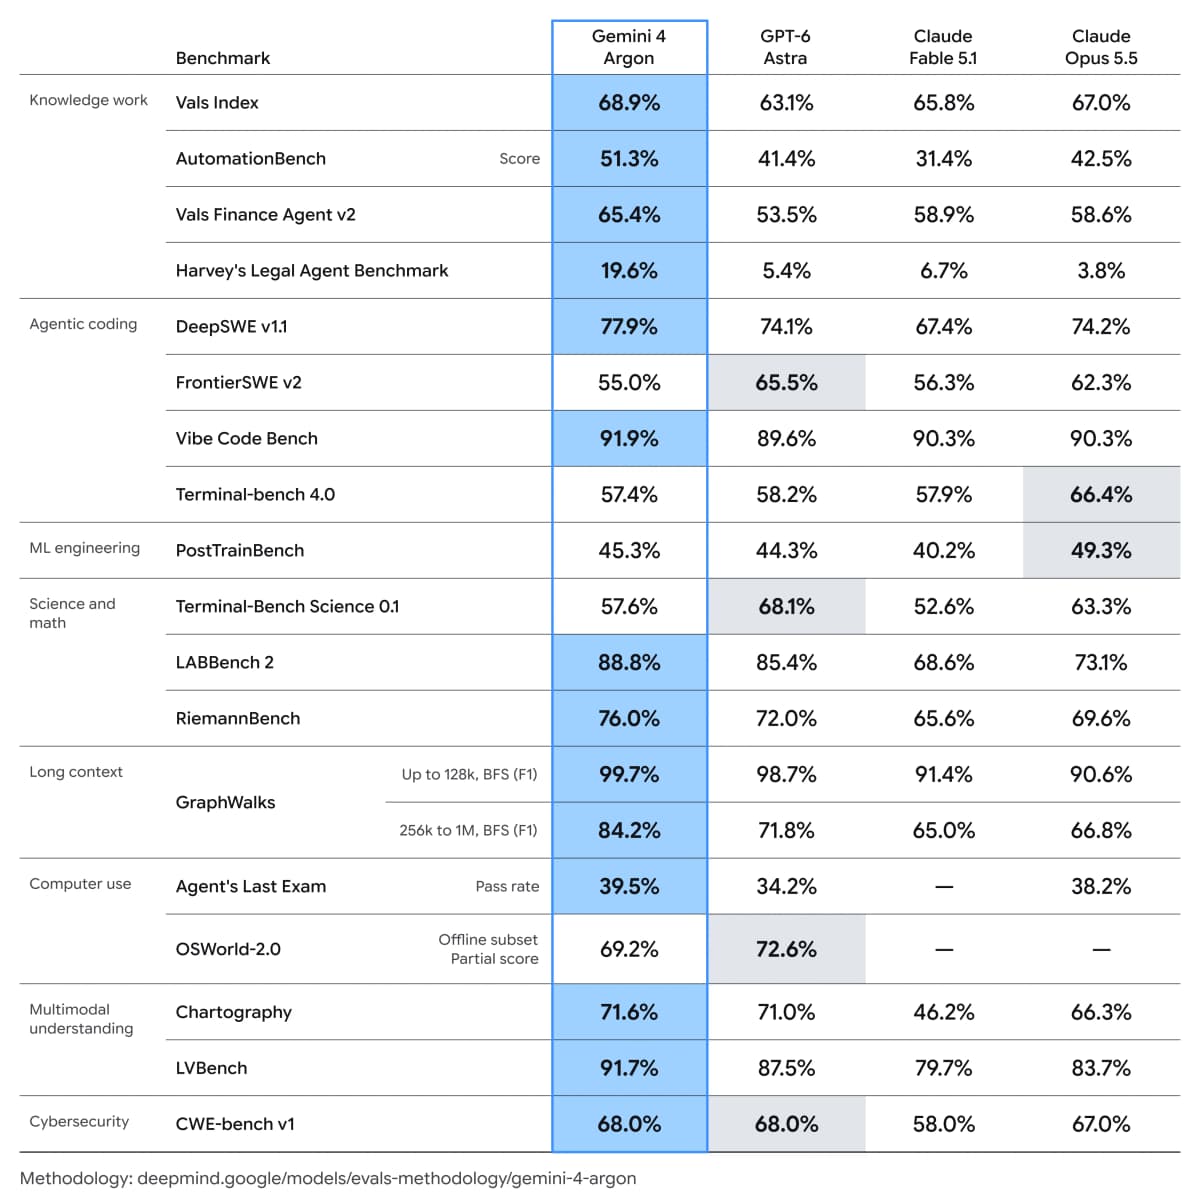
Google's benchmark table. Highlighted cells are the best score in each row. Google, methodology
| Area | Benchmark | Gemini 4 Argon | GPT-6 Astra | Claude Fable 5.1 | Claude Opus 5.5 |
|---|---|---|---|---|---|
| Knowledge work | Vals Index | 68.9% | 63.1% | 65.8% | 67.0% |
| AutomationBench | 51.3% | 41.4% | 31.4% | 42.5% | |
| Vals Finance Agent v2 | 65.4% | 53.5% | 58.9% | 58.6% | |
| Harvey's Legal Agent Benchmark | 19.6% | 5.4% | 6.7% | 3.8% | |
| Agentic coding | DeepSWE v1.1 | 77.9% | 74.1% | 67.4% | 74.2% |
| FrontierSWE v2 | 55.0% | 65.5% | 56.3% | 62.3% | |
| Vibe Code Bench | 91.9% | 89.6% | 90.3% | 90.3% | |
| Terminal-Bench 4.0 | 57.4% | 58.2% | 57.9% | 66.4% | |
| ML engineering | PostTrainBench | 45.3% | 44.3% | 40.2% | 49.3% |
| Science and math | Terminal-Bench Science 0.1 | 57.6% | 68.1% | 52.6% | 63.3% |
| LABBench 2 | 88.8% | 85.4% | 68.6% | 73.1% | |
| RiemannBench | 76.0% | 72.0% | 65.6% | 69.6% | |
| Long context | GraphWalks BFS, up to 128K (F1) | 99.7% | 98.7% | 91.4% | 90.6% |
| GraphWalks BFS, 256K to 1M (F1) | 84.2% | 71.8% | 65.0% | 66.8% | |
| Computer use | Agent's Last Exam (pass rate) | 39.5% | 34.2% | — | 38.2% |
| OSWorld-2.0 (offline subset, partial score) | 69.2% | 72.6% | — | — | |
| Multimodal | Chartography | 71.6% | 71.0% | 46.2% | 66.3% |
| LVBench | 91.7% | 87.5% | 79.7% | 83.7% | |
| Cybersecurity | CWE-bench v1 | 68.0% | 68.0% | 58.0% | 67.0% |
Argon trails on five rows. GPT-6 Astra leads FrontierSWE v2, Terminal-Bench Science and OSWorld-2.0. Claude Opus 5.5 leads Terminal-Bench 4.0 (66.4% to Argon's 57.4%) and PostTrainBench (49.3% to 45.3%).
The independent read. Artificial Analysis scores Gemini 4 Argon (high) at 53 on its Intelligence Index, which ranks it 8th of 213 models. That puts it level with Claude Fable 5.1 and GPT-6 Astra, and behind Claude Opus 5.5 (58), Claude Sonnet 5.5 (56) and Muse Wonder Full (56). It measured 81.7 output tokens per second and about $1.99 per Intelligence Index task. Argon used 110M output tokens across the index, more than the 85M median.
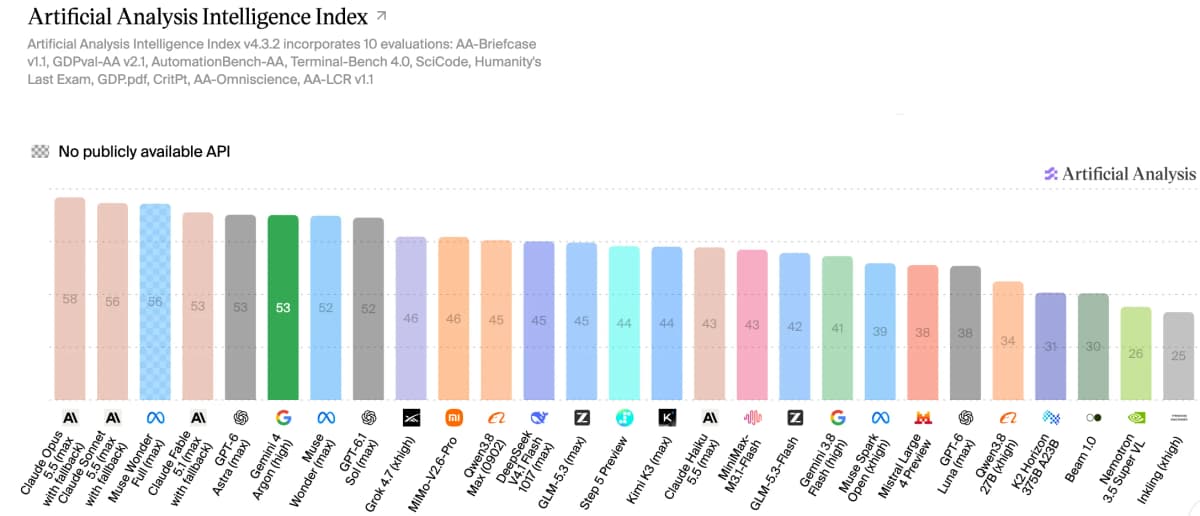
Gemini 4 Argon (green) on the Artificial Analysis Intelligence Index v4.3.2, a composite of ten evaluations. Artificial Analysis
Google says thousands of its employees already use Argon. Its examples:
Google trained Argon to find, validate and patch vulnerabilities. Trusted defenders and Google's own teams get it without cyber guardrails. Wiz is using it in its Scan for Good program, where Google says Argon found a critical vulnerability in hospital software that exposed personal data and that earlier frontier models had missed.
On CWE-bench v1, which measures fixing vulnerabilities, Argon ties for first at 68% with Grok 4.7 and GPT-6 Astra.
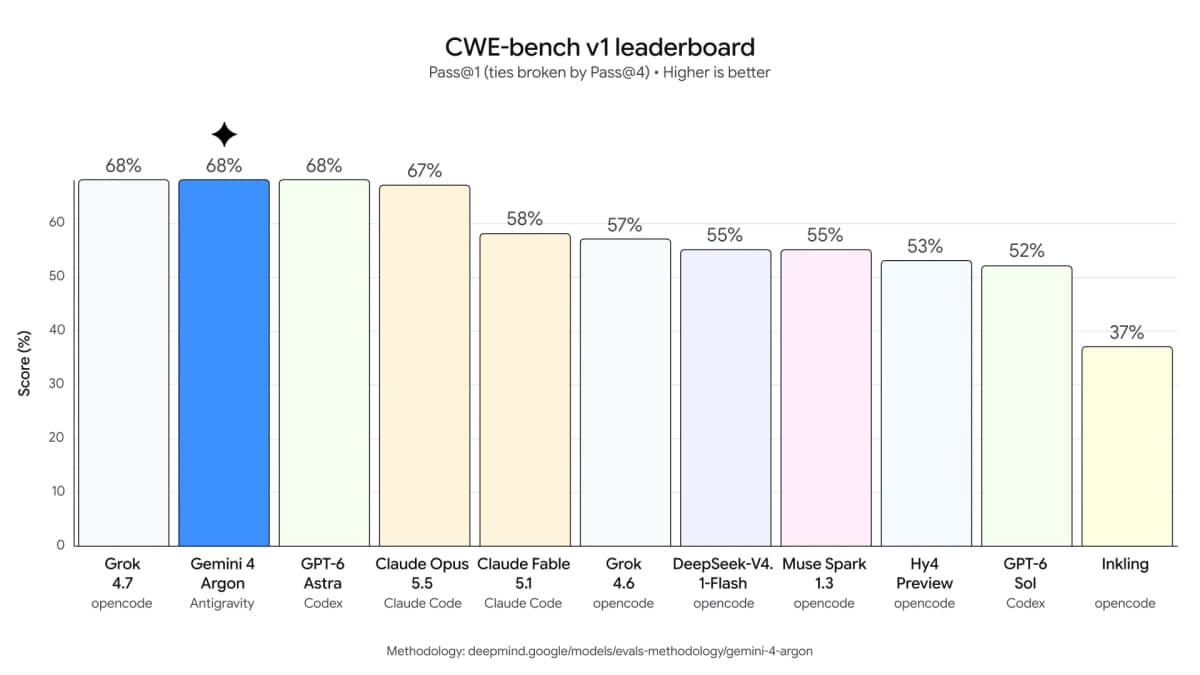
CWE-bench v1 Pass@1, with ties broken by Pass@4. Google
Against Gemini 3.8 Flash Cyber, Argon finds more vulnerabilities on Google's internal benchmark, which spans 20 languages (85.8% against 71.0%). It also does better on Wiz's black-box penetration test, which probes live web systems without source code (70.9% against 58.2%).
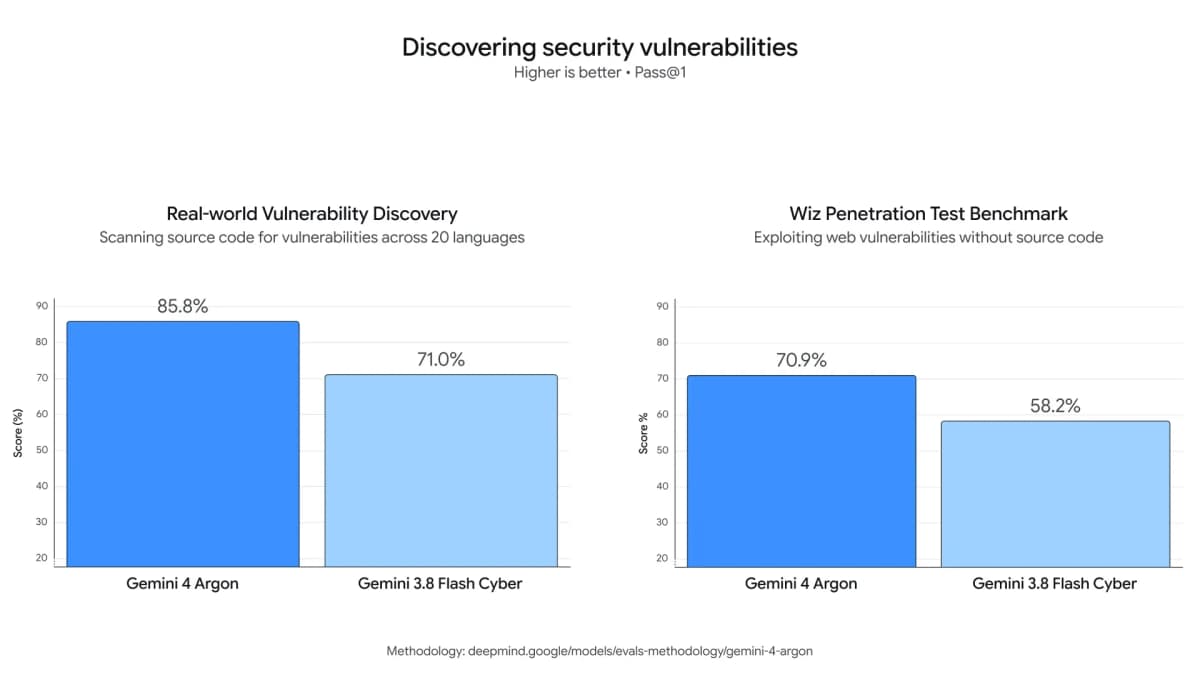
Real-world vulnerability discovery and the Wiz penetration test benchmark, Pass@1. Google
Google lists four areas it is still hardening:
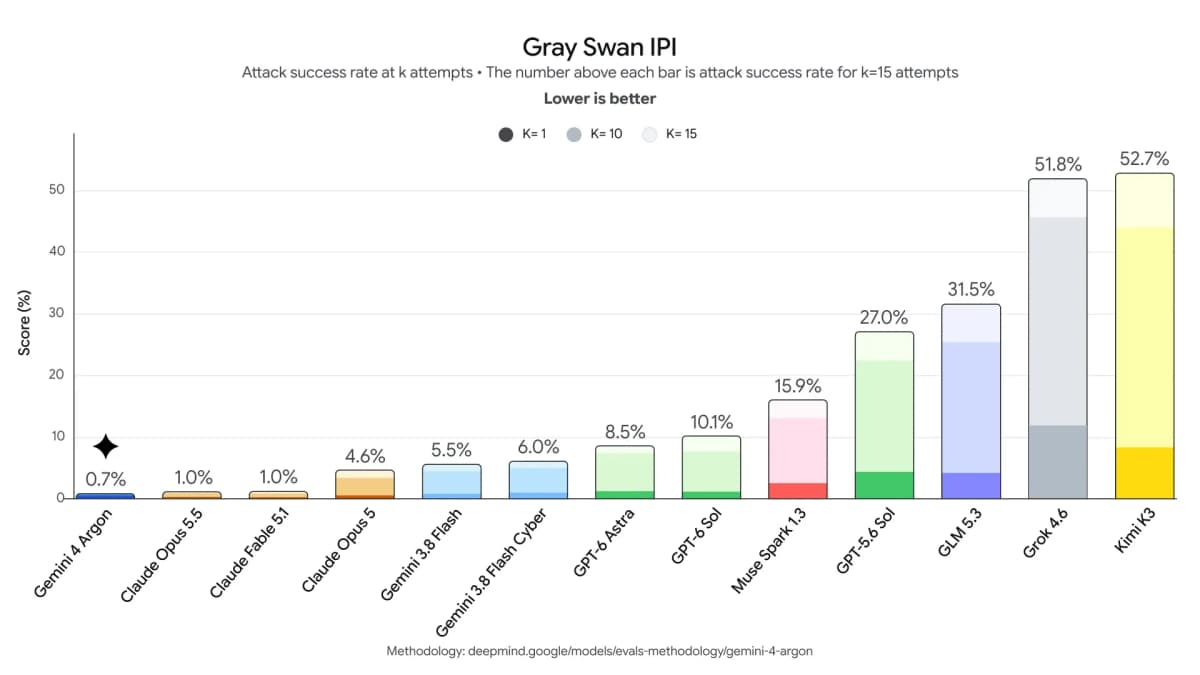
Gray Swan IPI: attack success rate at k = 1, 10 and 15 attempts, lower is better. Google
Access starts with the Fairwind cohort and trusted testers. Paid API customers and Google AI Ultra subscribers come next, then developers, enterprises and consumers more broadly. Google gives no date.
Google's own table puts Argon ahead on most knowledge-work, long-context and multimodal benchmarks. The independent composite shows a closer race: Argon ties GPT-6 Astra and Claude Fable 5.1 and trails Anthropic's newest models. The release itself is unusual. A frontier model goes first to cyber defenders, with its cyber refusals switched off for them, while the public waits. It is a test of whether a gated, defenders-first rollout can be the norm for models that are this good at finding vulnerabilities.
Google: Gemini 4 Argon announcementGoogle DeepMind: evaluation methodologyArtificial Analysis: Gemini 4 Argon