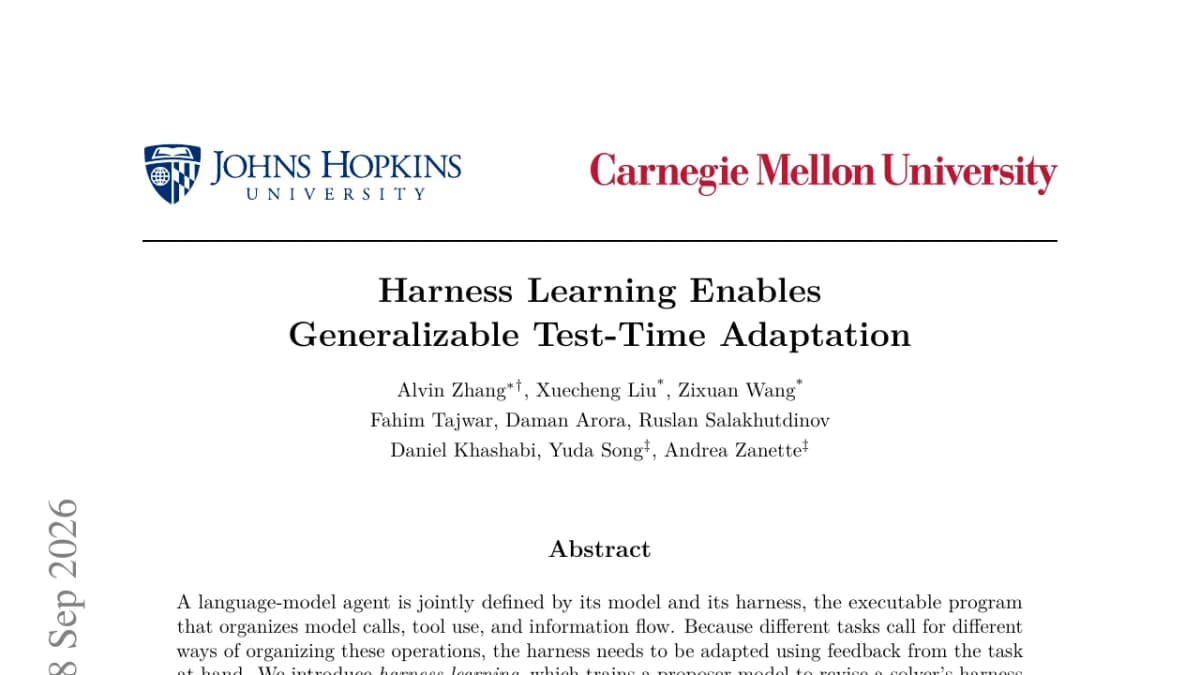
Harness Learning Enables Generalizable Test-Time Adaptation introduces a method for improving the executable program around a language-model agent. That harness controls model calls, tool use, and information flow.
A proposer model learns to revise a solver’s harness using execution feedback. Reinforcement learning rewards edits that improve task performance. At test time, the proposer continues to refine the program for new tasks while both models’ parameters remain fixed.
Experiments on reasoning and multi-hop question answering show improved revision quality and transfer to unseen tasks. Policies trained on individual revisions can also improve harnesses over successive rounds, although the benefits of training on revision sequences vary across settings.
The work treats agent control flow as an object that can adapt from experience. Its reported results concern the paper’s evaluation tasks rather than a general guarantee for every agent workflow.
Harness Learning Enables Generalizable Test-Time AdaptationPedro Domingos — source post