DeepSeek announced that DeepInfer, its in-house inference framework, is now fully open source. According to DeepSeek, it powers DeepSeek-V4.1-Flash at scale with high throughput and low latency. The company describes the release as sharing its production stack to help the community lower compute costs and reduce energy use.
- DeepSeek says DeepInfer is the framework it uses to serve V4.1-Flash in production, not a research prototype.
- The repository README lists optimized kernels (FlashMLA, DeepGEMM, DeepEP and others), DSpark speculative decoding with confidence-scheduled verification, attention data parallelism and MoE expert parallelism, bounded sliding-window replay, batch-invariant inference and structured outputs. It is Apache 2.0, needs Linux with Python 3.12 and CUDA 13 (or CANN 9.2), and supports NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs.
- It is offline inference only. A KV cache system, prefill/decode disaggregation and load balancing across replicas are not included, so it is not yet a complete serving stack. DeepSeek credits vLLM as its original base, with ideas from SGLang and TensorRT-LLM.
- The README publishes throughput curves for V4.1-Flash on SM100 GPUs, but no comparison with other engines. Users also asked for end-to-end throughput numbers on Ascend NPUs.
- Community reaction centered on the release of the full serving stack, kernels included, rather than just model weights.
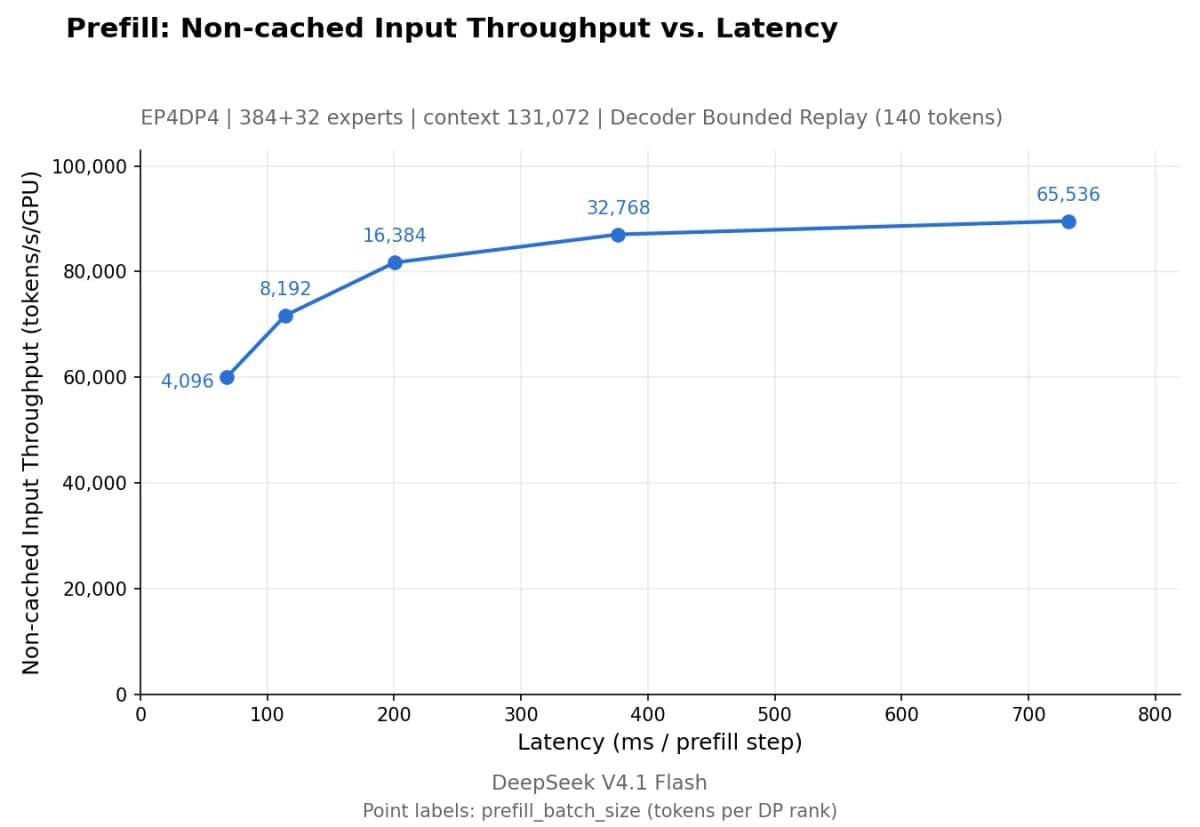
Prefill: non-cached input throughput against latency, on 4 SM100 GPUs. DeepInfer README
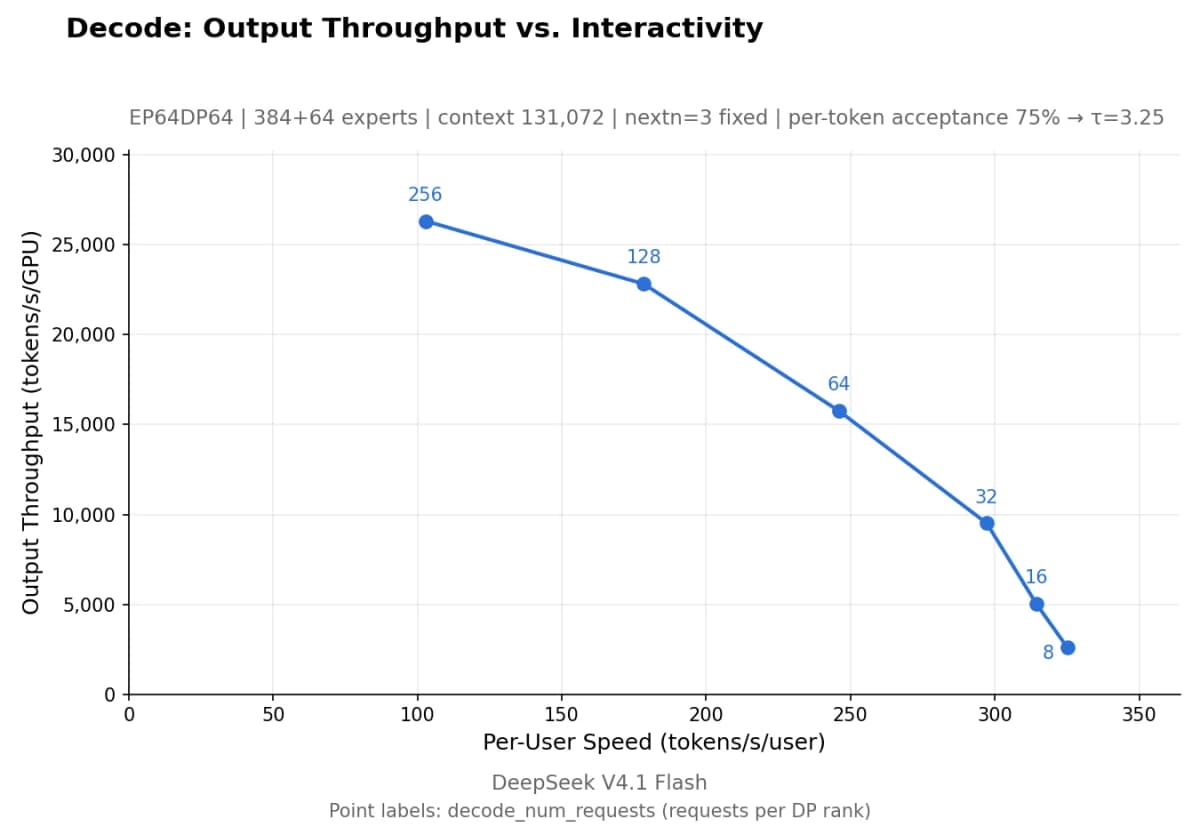
Decode: output throughput against per-user speed, on 64 SM100 GPUs. DeepInfer README
Open weights let others run a model, but serving it efficiently is usually the harder part. Publishing the production inference stack gives engineers a reference for how a frontier lab gets cost and latency down on real hardware. It also shows how that work is done on both NVIDIA and Huawei chips. Whether the community adopts it will depend on hardware support and independent benchmarks against existing engines such as vLLM. It follows DeepSeek's V4.1-Flash-1017 update, which focused on cheaper tasks.

