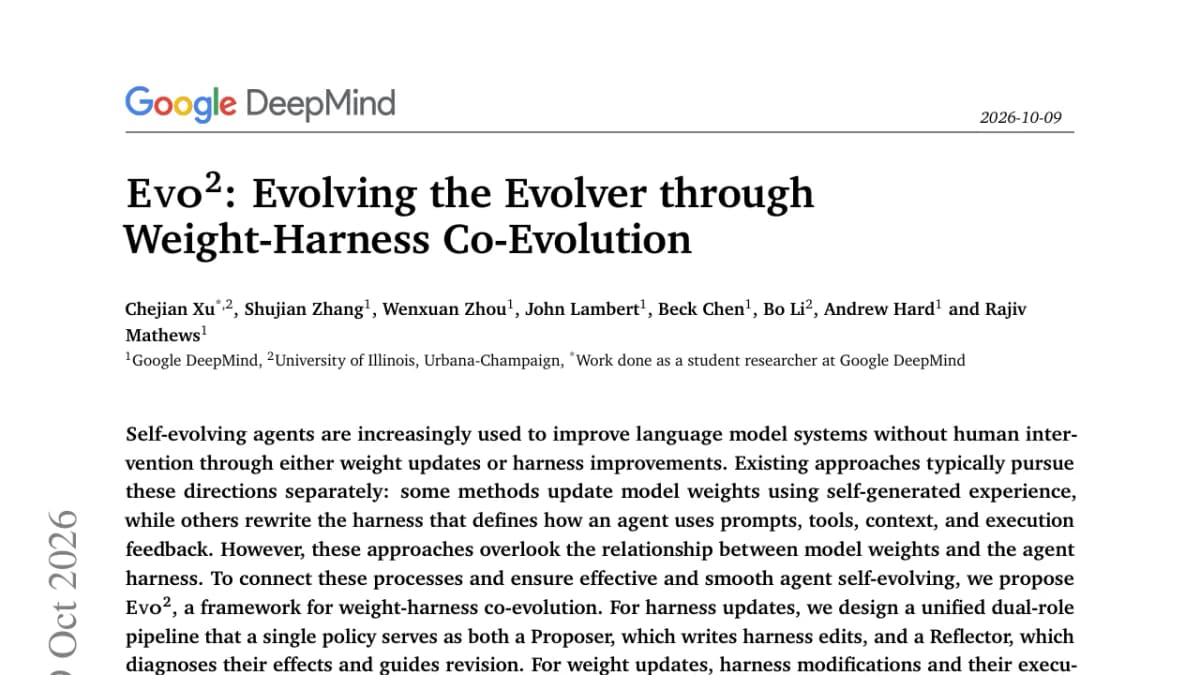
Evo² links two routes to improving coding agents: updating model weights and changing the program that controls prompts, tools, and execution.
A single policy acts as a Proposer, writing harness edits, and a Reflector, diagnosing their effects. The edits and execution results then supply training data for both roles. EvoTIDE combines supervised fine-tuning with interleaved reinforcement learning.
The authors report 82.1% on Polyglot and 48.3% on SWE-bench Verified, compared with 62.6% and 41.0% for the strongest respective baselines. Evolved harnesses also transfer across benchmarks without further evolution.
For proprietary models, the harness-improvement component alone raises a GPT-5-mini agent’s SWE-bench Verified result from 24.4% to 48.3%, without updating that model’s weights.
These are preprint results under the paper’s experimental conditions, rather than evidence of universal autonomous improvement.
Evo²: Evolving the Evolver through Weight-Harness Co-EvolutionDAIR.AI paper overview