
Samip introduced Noise on October 12 as a speedrun for pretraining without backpropagation. The project follows the team's Dust work, which the announcement describes as approaching backpropagation with SGD for transformer pretraining.
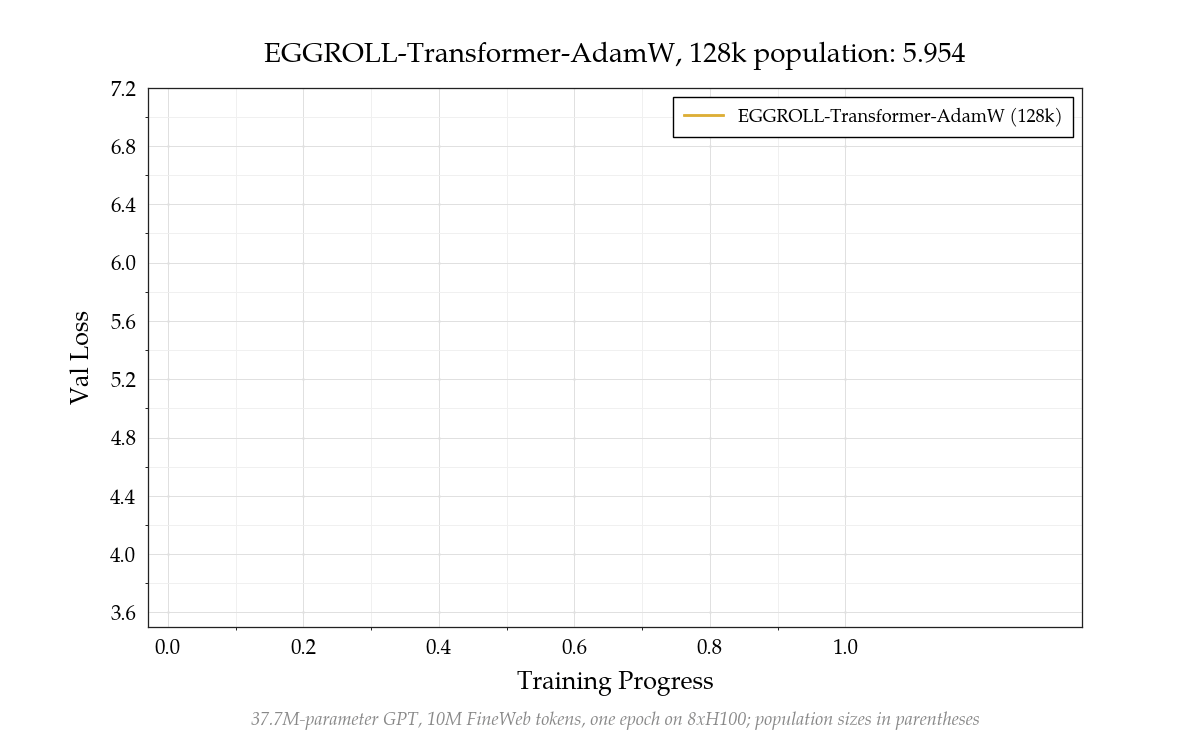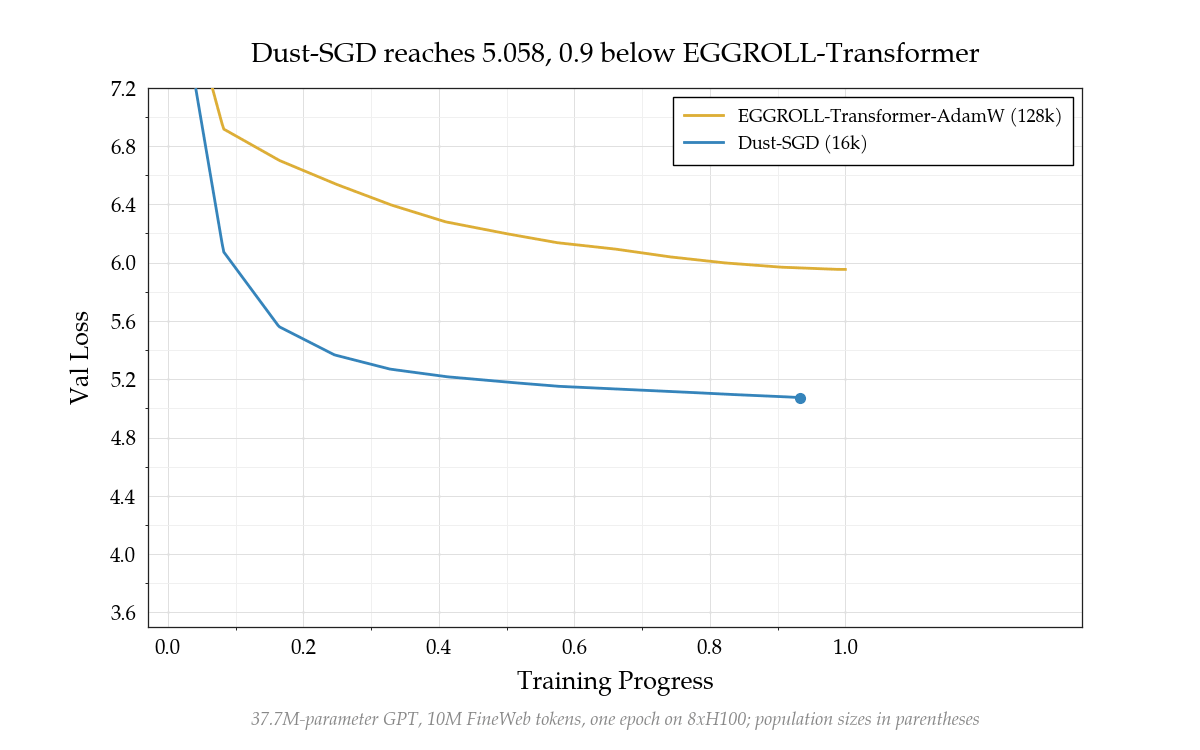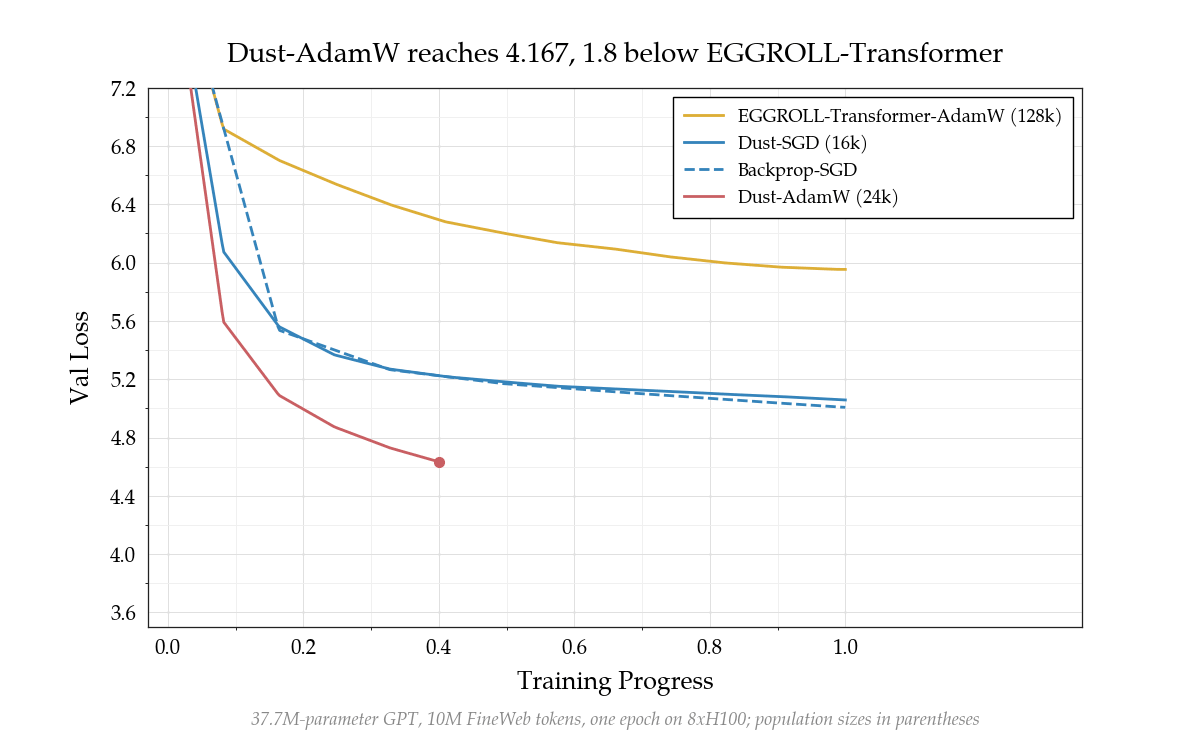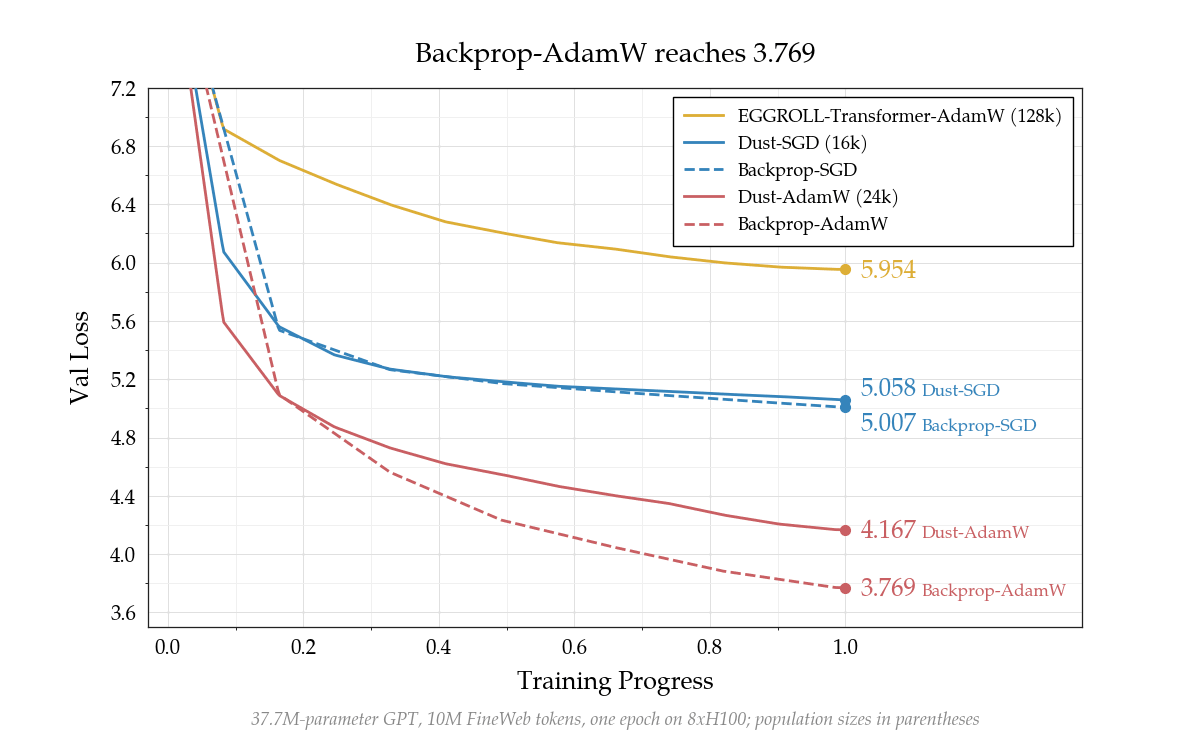
Noise’s animated baseline comparison: Dust matches backpropagation with SGD; with AdamW, it trails backpropagation while outperforming EGGROLL-Transformer in this benchmark. Animation: QLabs’ Noise project post.
The broader direction is zeroth-order optimization: investigating training methods that do not rely on the usual backpropagation of gradients through the model. Noise is intended to make it easier to iterate on that research and compare improvements in an open setting.
The team argues that further progress will require co-designing credit assignment, optimizers, model architectures, and eventually hardware. Its suggestion that another 1,000-fold improvement may be possible is an ambition, not a result established by the announcement.
The immediate contribution is the speedrun and its public implementation. Whether this approach can replace backpropagation at larger scales remains a question for measured comparisons across compute budgets and training quality.
Sources: Announcement, GitHub repository, Project post.