
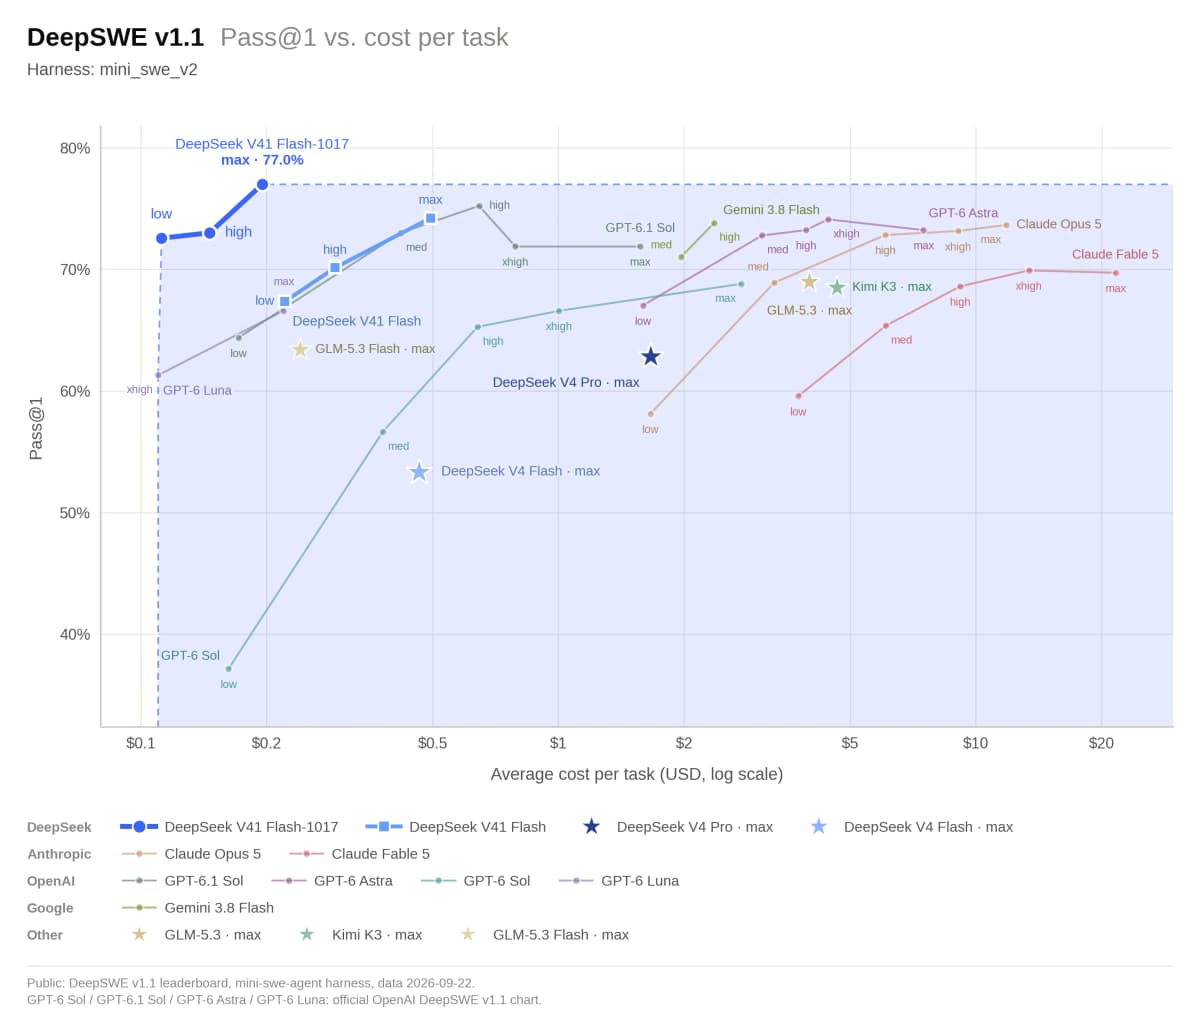
DeepSeek-V4.1-Flash-1017 launched on October 17, 2026, bringing stronger reasoning, coding, agent, and visual results alongside shorter outputs and faster task completion. The update is live on DeepSeek’s website, app, and API. DeepSeek describes it as an advance in the performance–cost Pareto frontier: completing more tasks successfully while spending less per task. Launch announcement.
This is the October refresh of the V4.1-Flash family introduced in September. Search and Fetch APIs were announced in the same thread, but the model update is the main release. API users access it through the existing deepseek-flash name; October’s token prices and calling method are unchanged. Changelog.
A Pareto frontier marks the best available trade-offs: an option lies off the frontier when another is both cheaper and at least as capable. DeepSeek’s claim is that the new model shifts that boundary outward, rather than gaining accuracy only by spending more on reasoning.
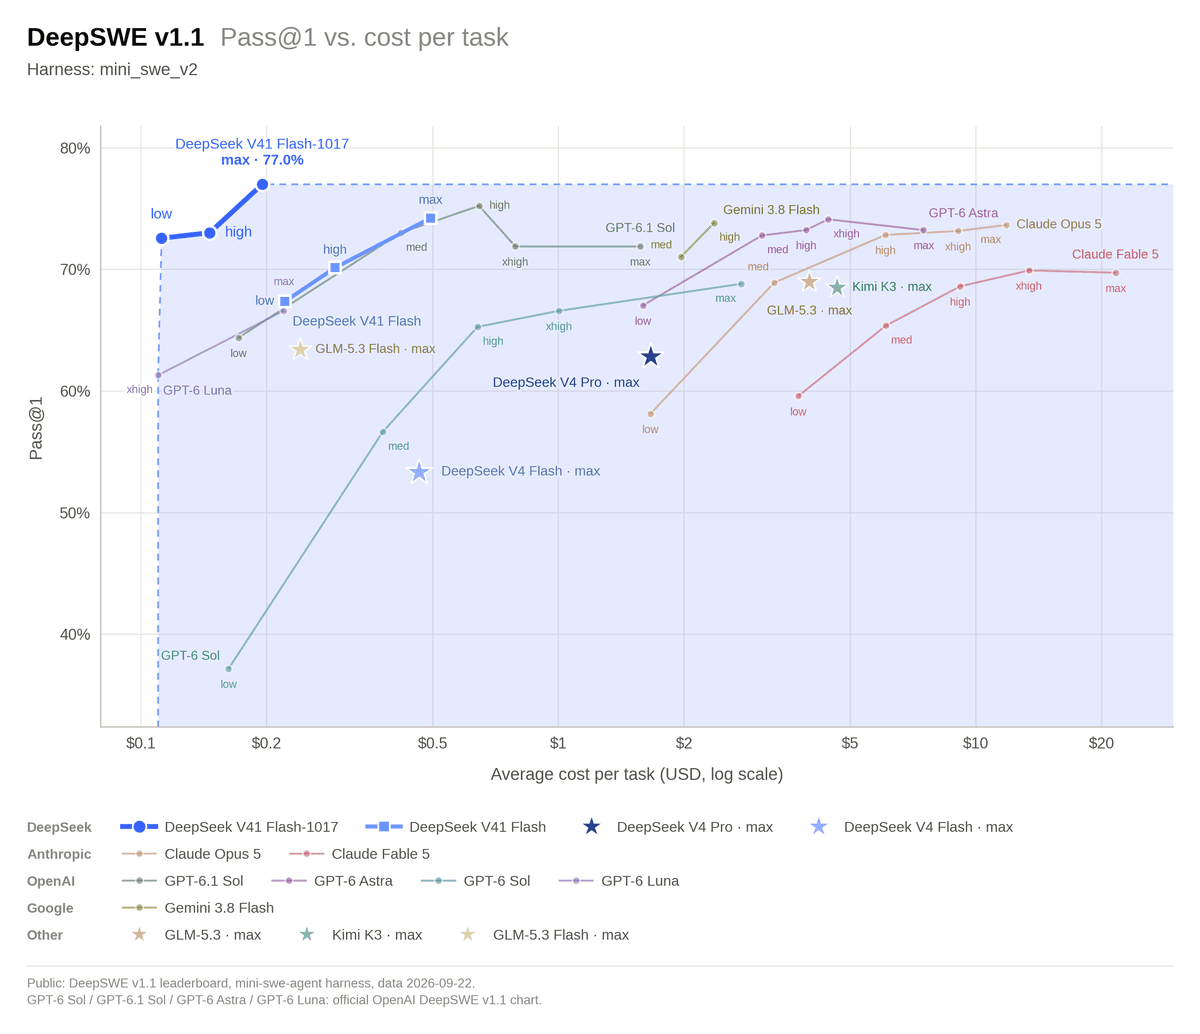
DeepSeek’s performance–cost comparison on DeepSWE v1.1, using the mini-swe-v2 harness. Cost uses a logarithmic scale. Official launch chart.
In this chart, the new model at maximum effort reaches 77.0% Pass@1 at roughly $0.20 per task, compared with the previous V4.1-Flash maximum-effort point at 74.2% and roughly $0.50. Reading those approximate coordinates gives about 60% lower task cost, alongside a 2.8-point improvement in success rate. The dollar values and reduction are estimates from the plotted positions, not a separately published exact savings figure.
The new low- and high-effort settings also move above and to the left of the previous model’s corresponding points. These are DeepSeek’s reported benchmark results; they do not establish a universal ranking across workloads. The release attributes the efficiency gain to shorter outputs and reduced task runtime, without publishing one overall percentage reduction for either. Release notes.
The official comparison reports gains on all eleven listed benchmarks. The table below compares the previous V4.1-Flash with the October 17 refresh; changes are score points. Model card.
| Benchmark | Previous V4.1-Flash | V4.1-Flash-1017 | Gain |
|---|---|---|---|
| HLE, without tools | 36.8 | 42.6 | +5.8 |
| Terminal-Bench 4.0 | 31.2 | 42.3 | +11.1 |
| DeepSWE v1.1 | 74.2 | 77.0 | +2.8 |
| ProgramBench | 20.3 | 29.1 | +8.8 |
| NL2Repo-Bench | 65.4 | 68.2 | +2.8 |
| Automation-Bench v1.0.6 | 54.8 | 60.5 | +5.7 |
| Agents’ Last Exam | 31.8 | 35.4 | +3.6 |
| Apex Bench v1.1 | 64.6 | 72.1 | +7.5 |
| Chartography, with tools | 78.9 | 83.0 | +4.1 |
| BabyVision, with tools | 89.6 | 92.5 | +2.9 |
| ZeroBench-main, with tools | 49.0 | 51.0 | +2.0 |
Evaluation details matter: HLE’s text-only subset rises separately from 39.1 to 44.0. Terminal-Bench 4.0 uses Claude Code, DeepSWE uses Mini-SWE-V2, and ZeroBench-main uses Pass@5. These scores measure different tasks and protocols and should not be combined into one average. Evaluation notes.
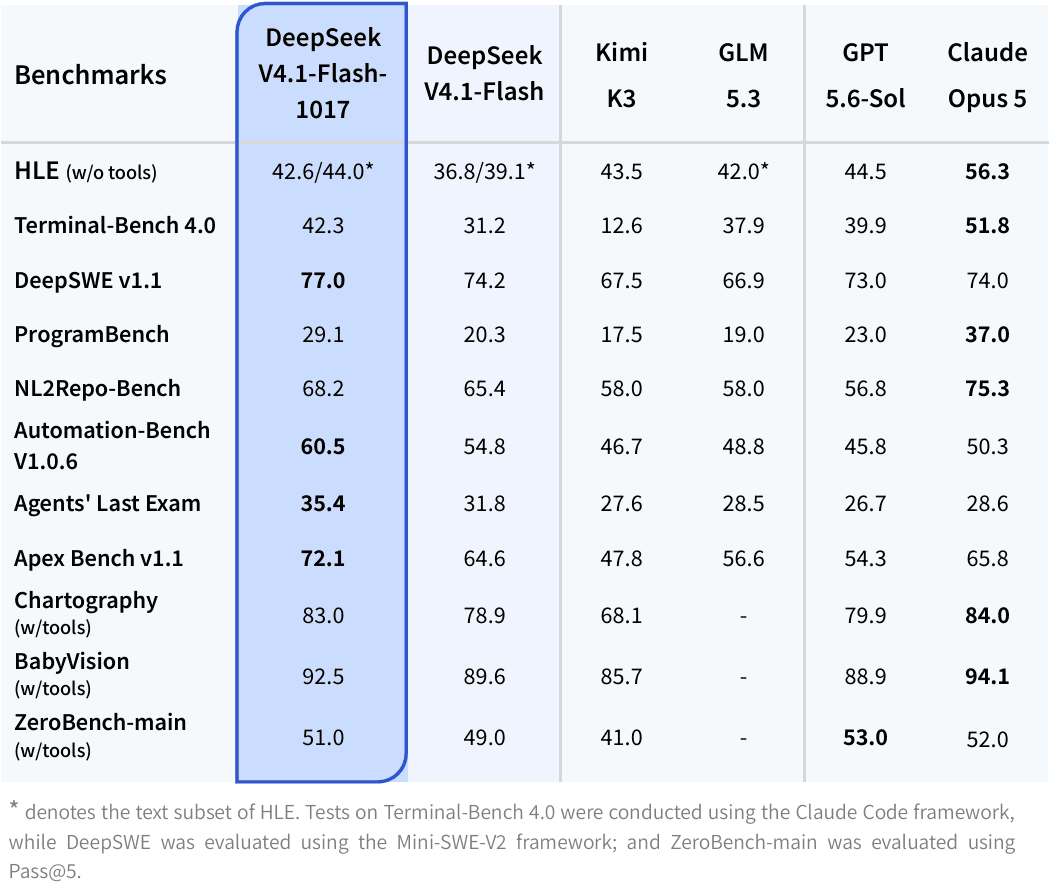
The complete comparison published by DeepSeek, including other models and evaluation footnotes.
The October improvement is lower cost to complete work at unchanged token rates. A shorter successful run can use fewer billed tokens; it does not require a new price cut. Actual savings depend on the task, reasoning effort, cache use, and whether additional attempts are needed.
The earlier September launch had already reduced API prices and introduced architectural savings. DeepSeek described V4.1-Flash as a 552B-parameter mixture-of-experts model with an asymmetric Causal Encoder–Decoder: 8B parameters active for input and 16B for output. It reported a KV cache using one-quarter the HBM and one-eighth the SSD storage of the previous generation—75% and 87.5% reductions respectively. These are September’s architecture claims, not new October reductions. September announcement; technical report.
Current official Flash prices, checked October 19, are in US dollars per million tokens:
| Token category | Peak | Off-peak |
|---|---|---|
| Cached input | $0.006 | $0.003 |
| Uncached input | $0.30 | $0.15 |
| Output | $1.20 | $0.60 |
Off-peak rates are 50% lower. Peak periods are 01:00–04:00 and 06:00–10:00 UTC on weekdays, excluding Chinese public holidays; weekends and other hours are off-peak. Official pricing.
DeepSeek says reinforcement learning with self-feedback improves building projects from scratch. Its demonstrations include a Forbidden City 3D model, a browser racing game, a Portal 2 recreation in Godot, and Valley of Ages, a 3D scene spanning prehistoric to modern times. These are selected demonstrations rather than a general success-rate measurement. Project examples.
The model has been optimized for DeepSeek Harness, Tencent CodeBuddy, WorkBuddy, and other platforms. DeepSeek recommends Harness v0.2.1-rc.1 or later. The API continues to offer a 1M-token context window, up to 384K output tokens, vision, thinking and non-thinking modes, tool calls, JSON output, and Responses and Anthropic API support. These are supported capabilities, not all newly introduced in this refresh. Launch guidance; API specifications.
The updated model weights and repository are available under the MIT license on Hugging Face, with a ModelScope release also linked by DeepSeek. The model card supplies reference prompt encoding and inference instructions and introduces the deepseek-recipe toolkit for handling prompt and response formats.
The same launch also opens standalone Search and Fetch access at $0.75 per 1,000 successful requests for each endpoint. Integrated server-side calls in DeepSeek Harness, Claude Code, and Codex remain temporarily free for DeepSeek API users; billing starts October 31, 2026, at 16:00 UTC. This tool charge is separate from model token pricing. Search and Fetch announcement; billing rules.
DeepSeek: V4.1-Flash-1017 launch threadOctober 17 release and project demonstrationsDeepSeek changelog: October update and unchanged pricingV4.1-Flash-1017 model card, benchmarks, and weightsOfficial models and pricingSeptember V4.1-Flash architecture and pricing announcementTechnical report: Pushing the Limits of KV Cache CompressionDeepSeek: complete-project demonstrationsDeepSeek: Search and Fetch release