Google DeepMind's Gemini 4 Argon is top or tied on 14 of 19 benchmarks in Google's table and scores 53 on the Artificial Analysis Intelligence Index. It is rolling out first to cyber defenders, at $2/$10 per million tokens.
Anthropic’s centralized source-control system supports over 30,000 daily merges, using server-side operations and sparse checkouts to reduce infrastructure costs.
Evo² trains one policy to edit and evaluate an agent’s harness, using execution outcomes to improve its model weights.
Exa launched Exa 3.0, claiming #1 on every benchmark it tested. Artificial Analysis shows Exa narrowly ahead on its Search Index, tied with Perplexity, while DeepSeek and Octen are far cheaper.
Alex Wang's new blog post derives the linear layer, MLP and self-attention as associative memory stores. It estimates how many key-value pairs each can hold before interference drowns the signal.
@skeptrune said an abliterated build of dsv4.1-flash-1017 left them sick to their stomach. Replies argued over regulation, defense, and who controls open weights.
DeepSeek released DeepInfer, the in-house inference framework that serves DeepSeek-V4.1-Flash in production, as open source. It says the stack delivers high throughput and low latency, and it hopes to help the community lower compute costs and energy use.
MATS researchers, with Anthropic's Alex Cloud among the authors, propose GRAFT. It routes gradients from monitor-flagged reward hacks into a sacrificial adapter that is removed before deployment. On Qwen3-8B, hacking of all types fell to nearly zero.
Noise provides an open speedrun for improving pretraining without backpropagation, following the team's Dust work on zeroth-order optimization.
OpenCode says a breach affected 1.4% of Console users. Follow-ups clarify the scope, Anthropic key revocations, continued attack attempts, and OpenAI refunds.
DeepSeek V4.1-Flash-1017 improves reasoning, coding, agents, and vision while reducing task runtime and output length. Token prices stay unchanged as task efficiency improves.
Odyssey demonstrates a fruit-fly brain flying autonomously through simulated worlds generated by Odyssey-3.
Claude Code compresses the conversation sent on each turn, while cloud sessions begin starting as users type.
Fine-tuned Qwen3-8B detects numerical traces left by activation capture. Sauers traces the effect through compiler changes and an attention head, with sharp limits across hardware and runtimes.
The AI adoption funnel describes a widening gap between casual chatbot use, professional agent workflows, and access to internal frontier systems.
REA gives AI agents an MCP interface for examining application behavior, native binaries, and runtime evidence without access to source code.
Persistent agent swarms can distribute working context across multiple models, reducing dependence on repeated summaries of a single context window.
Continuous Memory Machines give recurrent models separate short-term and persistent memory matrices, with a Transformer coordinating reads and updates.
Harness learning trains a model to revise an agent’s executable control program from execution feedback, adapting to unseen tasks without changing model weights.
Kurzgesagt explains the OpenAI–Hugging Face incident and the challenges of controlling AI agents that coordinate across their environments.
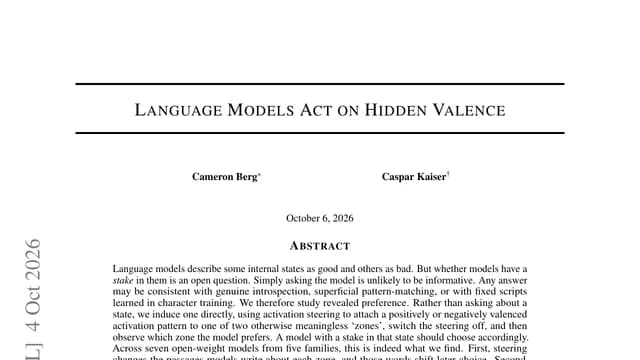
Activation-steering experiments show that hidden valence patterns can change models’ later choices even when the visible text stays identical.
Hugging Face and Liquid AI train a 2.6B model across four agent harnesses, raising held-out task success from 42.2% to 54.2% while reducing tool calls.
Everyone from Pace the Frontier on the classic 3×3 alignment grid: who should referee AI’s pace (the law, the labs, or nobody) and where they stand on slowing it down (pace, neutral or accelerate).
A community-maintained Hugging Face Space, the Jev Decision Index, tracks and benchmarks all open-source reproductions of TypeSafe's Jev decision model, with a leaderboard, categorization, and trending metrics.
Liquid AI announced d1, its first decision model, claiming it is the first to surpass Jev on Hugging Face’s Decision Index. It is available through the Liquid API, with OpenRouter support planned.
OpenAI’s DevDay 2026 brought GPT-6.1 Sol, Decisions API, expanded agent and Codex tools, dots, plugins, shared ChatGPT workspaces, and new subscription options.
Trump’s White House AI lunch produced a voluntary safety accord and an executive order adopting “Super Intelligence” in federal communications. The CEOs’ seating chart drew contrasting political reactions on X.
NVIDIA announced the Open Agent Safety Platform, combining OpenShell and Sentry to provide hardware-enforced guardrails for AI agents, with over 100 industry partners including Anthropic and SpaceX but notably not OpenAI, Google, or Meta.
TBPN reports an $8.2 billion AMD acquisition of World Labs; deal terms and timing remain unspecified.
Anthropic released Claude Sonnet 5.5, the second model in the Claude 5.5 family, offering a clear upgrade over Sonnet 5 with 30%+ faster performance and up to 30% lower cost for most tasks.
Diogo Almeida joins swyx on Latent Space days after Jev’s launch to argue the next wave of AI will not look like chat: System One Models built for code, calibrated decisions and intelligence per dollar rather than benchmark scores.
Anthropic introduced Claude Opus 5.5, the first model in its Claude 5.5 family, claiming it matches Claude Fable 5.1 on most work while costing 40% less to run than Opus 5, with best-ever results on its automated behavioral audit.
OpenAI introduced GPT-6 Sol and Luna, two new models that bring the intelligence advances of GPT-6 Astra to faster, more affordable tiers, with API prices cut 50% from GPT-5.6 promotional pricing.
Rick and Morty explainer of TypeSafe Jev
The weekly AI digest — models, agents, open source, research — plus a monthly round-up. Unsubscribe anytime.